Models in the browser
The short version
A Gemma 4 LLM can run live inference entirely inside a browser tab, with no internet, server, API key, or per-query cost after first load.
Live demo (tax prep proof-of-concept): webgpu-poc-182505046910.us-central1.run.app · GitHub: madhudream/webgpu-gemma4-tax
72 hours. Zero sleep. One working demo. A Gemma 4 LLM running live inference inside a browser tab — no internet required after the first load, no server, no API key, no per-query cost. The proof-of-concept is tax prep. The pattern works for any domain.
<a id="the-idea"></a>The Idea — The Credit Wall Problem
AI apps charge per query via cloud APIs and cap usage with 'credits', but running a small model locally in the browser eliminates per-query cost entirely.
You've seen the screen. You open an app, tap the AI feature, and you get:
0 / 3 credits available. Upgrade to continue.
Maybe it's a writing assistant. A coding helper. A customer support bot. A document analyser. A language tutor. A recipe suggester. Doesn't matter — the UI is always the same. You used your free tokens, and now the app is asking you to buy more.
This isn't an accident. It's the business model. Every AI feature in every SaaS app today is a thin wrapper around a cloud API that charges per token. The app developer pays per query, passes the cost on as "credits", and the user hits a wall the moment the feature becomes genuinely useful.
The credit wall is everywhere:
- Notion AI — runs out mid-document
- Grammarly — premium features gated behind a subscription that's really just a token budget
- Canva AI — "You've used your monthly AI generations"
- GitHub Copilot — per-seat billing for what is fundamentally token consumption
- Every domain-specific app built on top of OpenAI/Anthropic/Gemini API
And the irony is: most of these apps answer the same bounded set of questions, from the same finite knowledge base, over and over. The knowledge doesn't change. The model doesn't need to be a frontier model like OpenAI or Claude. But every query still routes to a cloud API, burns tokens, and sends user data to a third-party server.
What if the credits never ran out — because the model was running locally, on the user's own GPU, with zero per-query cost?
That's the question this project answers.
I wanted to answer one question: what if the model ran in the browser, with the knowledge injected locally? On the user's own GPU. Zero server, zero tokens, zero per-query cost. Data never leaves the device.
That's not a new idea — WebLLM, Transformers.js, and the broader WebGPU ecosystem point in this direction. What was missing was:
- A model small enough to load in a browser tab without a $3,000 GPU
- A practical data pipeline to show the pattern working end-to-end on real domain knowledge
Gemma 4 solved problem 1 with two architectural innovations: TurboQuant and Per-Layer Embeddings (PLE). I built the proof-of-concept on problem 2 using IRS tax data — 3,088 PDFs, filtered and converted into 20,000 Q&A pairs.
The proof-of-concept is tax prep. The deployment pattern works for any domain.
By the Numbers
| Metric |
Value |
| Total build time |
~72 hours |
| IRS PDFs scraped |
3,088 |
| PDFs after filtering |
1,421 |
| Q&A training pairs generated |
~20,000 |
| Fine-tuning data pipeline cost |
~$5 (Claude API) |
| Per-query inference cost |
$0.00 |
| Model size (quantized) |
~600 MB |
| Deployment |
Static HTML + nginx + Cloud Run |
<a id="why-it-fits"></a>Why Gemma 4 Fits in a Browser: TurboQuant + PLE
Gemma 4's TurboQuant compression and Per-Layer Embeddings let a capable LLM shrink to ~600 MB, small enough to run in a browser tab on integrated GPU.
Before we get to the build, we need to understand why this is even possible in 2025 when it wasn't in 2023. Two architectural innovations in Gemma 4 are the reason: TurboQuant and Per-Layer Embeddings (PLE). Without them, fitting a capable LLM into a browser tab would require either a very small, dim model or a $3,000 desktop GPU.
TurboQuant — Two-Step Compression
Standard quantization compresses a model by reducing weight precision (e.g., 32-bit floats → 8-bit integers). TurboQuant goes further with a two-stage approach that gets dramatically better compression with less quality loss.
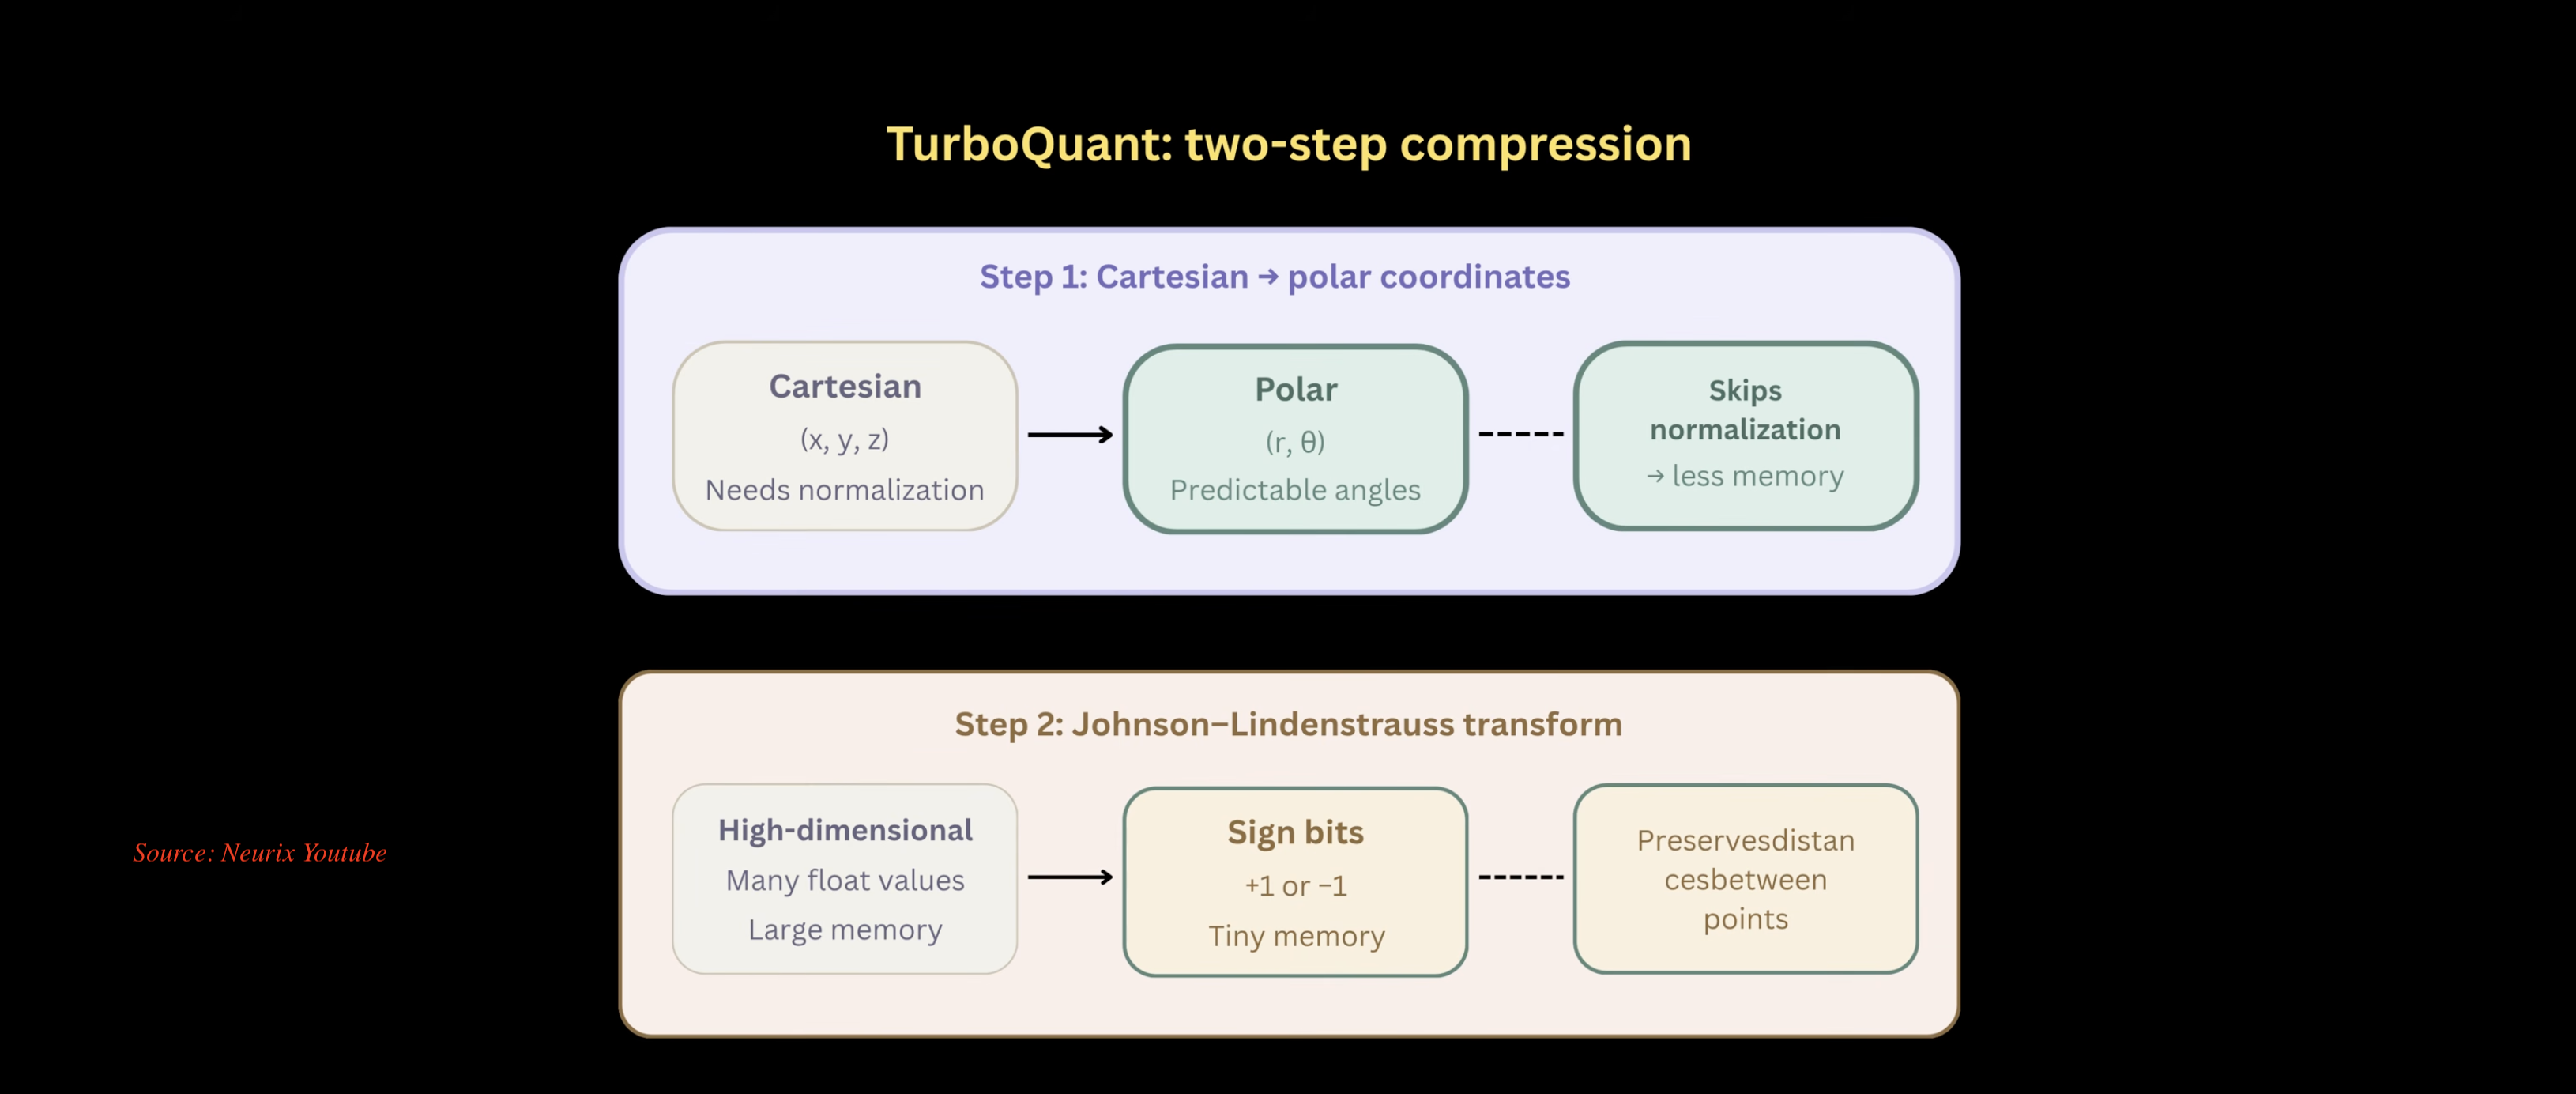
Step 1 — Cartesian → Polar coordinates
Model weights are normally stored as $(x, y, z)$ Cartesian coordinates. Converting to polar $(r, \theta)$ representation means the angles become highly predictable and regular. The critical side-effect: normalization can be skipped, which sheds a significant chunk of memory overhead.
$$\text{Cartesian}(x, y, z) \xrightarrow{\text{TurboQuant Step 1}} \text{Polar}(r, \theta) \text{ — skips normalization}$$
Step 2 — Johnson–Lindenstrauss transform
The polar-converted weights are then projected through a Johnson–Lindenstrauss (JL) transform. The JL lemma guarantees that you can reduce high-dimensional data to sign bits (+1 or −1) while preserving the relative distances between points. Think of it as flattening a complex weight landscape down to a binary map that still captures all the meaningful relationships.
$$\text{High-dim floats} \xrightarrow{\text{JL transform}} \text{Sign bits} {+1, -1} \text{ — tiny memory, distances preserved}$$
The combined result: a ~600 MB quantized model (q4f16) that fits comfortably in the VRAM of an integrated GPU — the kind found in any mid-range laptop made after 2022.
q4f16 in plain English: 4-bit integer weights (TurboQuant-compressed) + 16-bit float activations. A model that would occupy 2.4 GB at full fp32 precision runs in ~600 MB. That's the difference between "needs a dedicated GPU" and "runs in a browser tab."
PLE — Per-Layer Embeddings
The second innovation addresses model quality at small sizes. Traditional small models inject all context into the token stream at the start and carry it through every layer. Per-Layer Embeddings take a smarter approach.
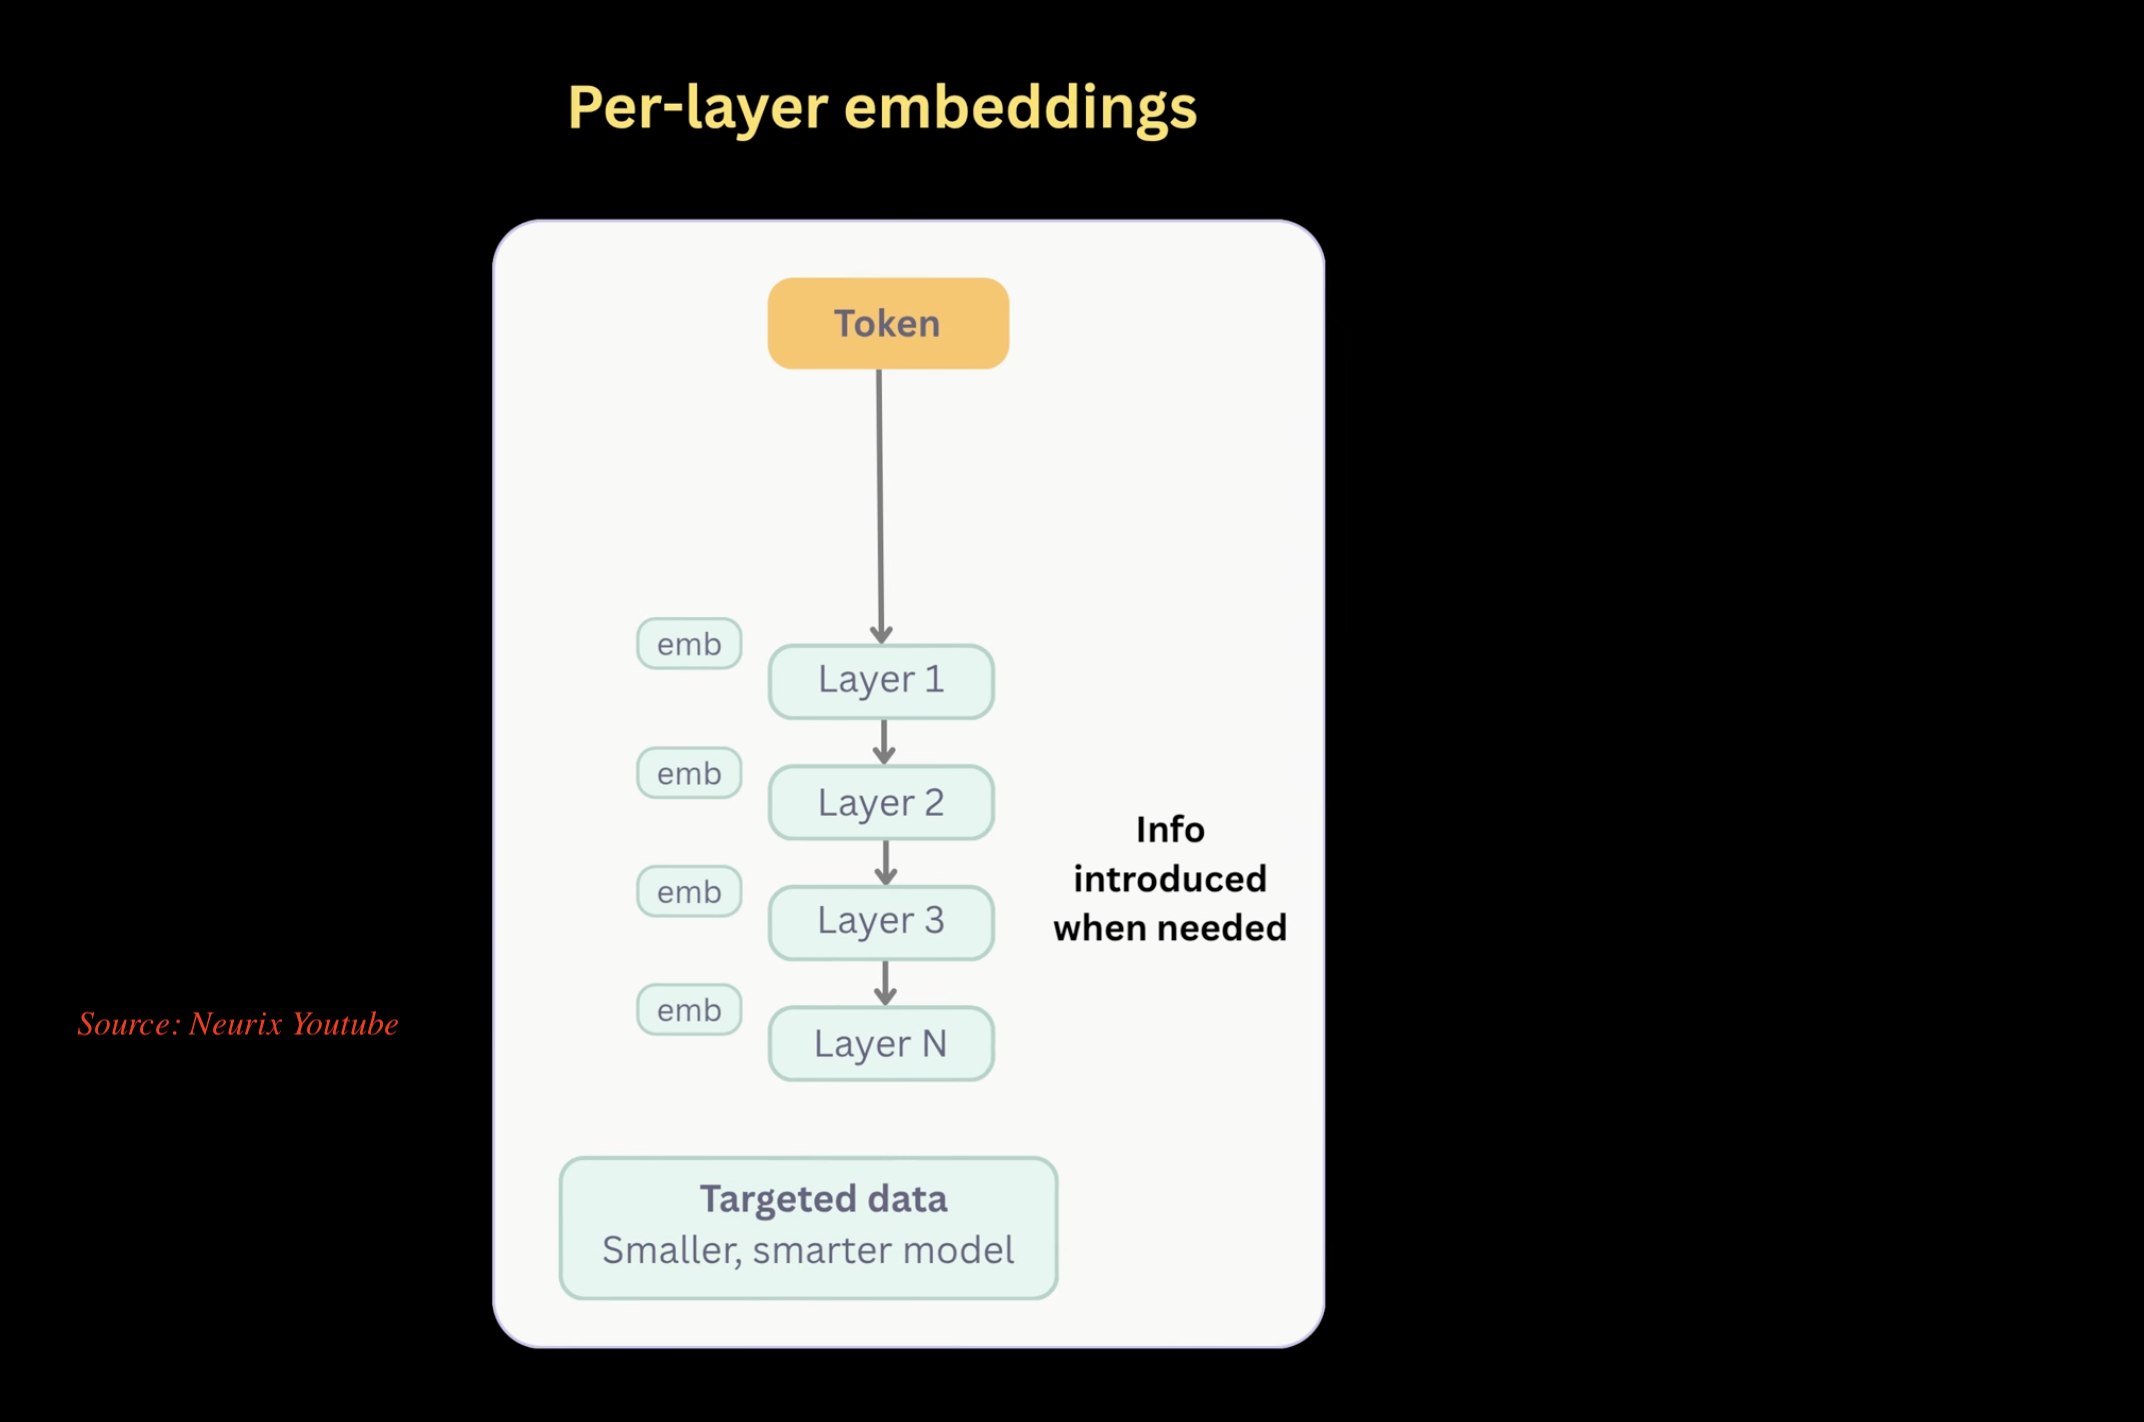
(Source: Neurix YouTube)
The Neurix channel has an excellent deep-dive on Gemma 4's architecture that covers both TurboQuant and PLE in detail — worth watching before diving into the code:
Instead of front-loading all embeddings, PLE introduces domain-specific information at each layer, only when that layer needs it. A token flows through Layer 1 → Layer 2 → Layer 3 → Layer N, and at each transition the model receives a fresh embedding injection targeted to that depth of reasoning.
The result: the same model parameters carry far more task-relevant signal per byte. You get:
- Smaller overall model — fewer parameters needed to achieve the same accuracy
- Smarter per-domain performance — embeddings are targeted to the task, not generic
- Better VRAM efficiency — context doesn't need to be propagated through the full weight stack from Layer 1
How They Work Together
| Property |
Without TurboQuant + PLE |
With TurboQuant + PLE |
| Model size at capability |
3–7 GB |
~600 MB |
| Quality at 600 MB |
Poor |
Production-usable |
| VRAM requirement |
Dedicated GPU |
Integrated GPU / browser |
| Load time (cached) |
N/A |
< 1 second |
| Per-query cost |
API tokens |
$0.00 |
This is why the browser runtime is viable in 2025. Not because browsers got faster (they did), and not because WebGPU is new (it isn't) — but because Gemma 4's compression architecture crossed the threshold where "browser GPU" became a real inference target.
The deployment pattern is:
- Load the ONNX model once → cached in IndexedDB
- Inject domain knowledge via RAG at inference time (or fine-tune it in permanently)
- Run unlimited queries locally — no server, no token counter, no data leaving the device
Tax prep is the proof-of-concept. Swap the IRS Q&A for medical billing codes, HR policies, legal precedents, product specs — the architecture is identical.
<a id="the-poc"></a>4 a.m. on April 13 — The POC
A proof-of-concept showed Gemma 4 can run entirely inside a browser tab via Transformers.js, answering domain questions with no server or API.
The first question was binary: does this actually work as a real deployment pattern? Can you load Gemma 4 in a browser tab via Transformers.js, inject domain Q&A at runtime, and get coherent answers — all without a server?
The answer, using the onnx-community/gemma-4-E2B-it-ONNX model on Hugging Face and Transformers.js: yes. And the tax prep demo is the thing I built to prove it.
// ai.js — the heart of the browser runtime
const MODEL_ID = 'onnx-community/gemma-4-E2B-it-ONNX';
const CDN      = 'https://cdn.jsdelivr.net/npm/@huggingface/transformers@4.0.1';

export async function loadModel() {
  const { AutoProcessor, Gemma4ForConditionalGeneration, TextStreamer } =
    await import(CDN);

  aiProcessor = await AutoProcessor.from_pretrained(MODEL_ID);

  aiModel = await Gemma4ForConditionalGeneration.from_pretrained(MODEL_ID, {
    dtype: 'q4f16',   // 4-bit integer + 16-bit float — small enough to fit in VRAM
    device: 'webgpu', // hands it off to the browser's GPU pipeline
    progress_callback: (info) => {
      if (info.status === 'progress') emit('loading', `Downloading… ${info.progress}%`);
    },
  });
}
The model loads once, lives in the browser's IndexedDB cache, and on every subsequent visit it starts cold in under a second from disk. The q4f16 dtype is the sweet spot — small enough that a mid-range laptop GPU handles it without sweating, sharp enough to give coherent answers.
Why q4f16 works here: TurboQuant's two-step compression (Cartesian→polar + Johnson–Lindenstrauss) gets Gemma 4 down to ~600 MB at this dtype — small enough for an integrated GPU, sharp enough for production answers. See the full explanation above.
That first morning proved the runtime was viable. Now came the hard part: what does the model actually know about taxes?
<a id="data-pipeline"></a>The Data Pipeline — Scraping the IRS
The full IRS forms catalog, 3,088 rows across 124 paginated pages, was scraped into one JSON file in about 20 minutes using Playwright.
If you want a model that knows about IRS forms, you need IRS forms. The official source is https://www.irs.gov/forms-instructions-and-publications — a paginated table with 124 pages and 3,088 rows.
Playwright got me every single one:
// scrape_irs_pdfs.js
const BASE_URL = 'https://www.irs.gov/forms-instructions-and-publications';
const LAST_PAGE = 123; // page=0 to page=123 → 124 pages × 25 = 3,088 actual rows

async function scrapePage(page, pageIndex) {
  const url = pageIndex === 0 ? BASE_URL : `${BASE_URL}?page=${pageIndex}`;
  await page.goto(url, { waitUntil: 'domcontentloaded', timeout: 60000 });
  await page.waitForSelector('table tbody tr', { timeout: 30000 });

  return await page.$$eval('table tbody tr', (trs) =>
    trs.map((tr) => {
      const linkEl = tr.querySelector('a[href*=".pdf"]');
      return {
        formNumber: tr.querySelectorAll('td')[0]?.innerText?.trim() || '',
        title:      tr.querySelectorAll('td')[1]?.innerText?.trim() || '',
        period:     tr.querySelectorAll('td')[2]?.innerText?.trim() || '',
        pdfUrl:     linkEl ? linkEl.href : null,
      };
    }).filter(Boolean)
  );
}
3,088 rows. One JSON file. The raw IRS catalog, scraped in about 20 minutes.
<a id="filtering"></a>Filtering 3,088 PDFs with Claude
A rule-based pass plus Claude Haiku batches trimmed 3,088 raw IRS PDFs down to 1,421 genuinely useful English tax documents.
Raw IRS data is messy. 3,088 entries include Spanish-language duplicates, Haitian Creole editions, Korean versions, obsolete forms, IRS internal procedural manuals, blank envelope templates, and statistics-of-income reports — none of which help a taxpayer on April 14.
First pass: a rule-based filter that caught the obvious cases.
// Language codes IRS uses in parentheses: (SP), (KO), (ZH-S), (VI)...
const LANGUAGE_CODE_PATTERN =
  /\(\s*(sp|ht|zh-s|zh-t|ko|vi|ru|ar|bn|fa|fr|guj|it|ja|km|pa|pl|pt|tl|ur)\s*\)/i;

function isNonEnglish(row) {
  if (LANGUAGE_CODE_PATTERN.test(row.formNumber)) return true;
  if (FOREIGN_TITLE_KEYWORDS.some((kw) => row.title.toLowerCase().includes(kw))) return true;
  return false;
}
Second pass: Claude Haiku in batches of 100, with a tightly scoped prompt.
// filter_with_claude.js
const SYSTEM_PROMPT = `You are an expert at categorizing IRS tax documents.
KEEP: Tax forms, schedules, instructions, tax publications.
REMOVE: Glossaries, internal IRS procedural documents, statistics reports,
        press kits, blank envelope templates, obsolete/revoked items.
Respond with ONLY a raw JSON array of 0-based indices to KEEP.`;

// Process 100 items at a time — fast, cheap, accurate
const batches = chunk(allItems, 100);
End result: 1,421 English-language PDFs covering Tax Year 2025. Less than half the raw list, but every file is something a real person filling out a real return would actually use.
Filtering breakdown: 3,088 raw → 2,100 after language codes stripped → 1,421 after Claude semantic filtering. The last ~680 dropped were genuine edge cases rules alone couldn't catch: obsolete revisions still listed as current, statistical compendiums with no utility for filers, and internal IRS procedural manuals that look like publications.
<a id="downloading"></a>1,421 PDFs Downloaded in One Script
A Node script with five concurrent workers, redirect-following, and timeouts downloaded 1,421 PDFs to a local folder in a couple of hours.
Five concurrent downloads, redirect-following, timeout handling, and resume-on-skip if a file already exists locally.
// download_pdfs.js
const CONCURRENCY = 5;

function download(url, dest) {
  return new Promise((resolve, reject) => {
    const proto = url.startsWith('https') ? https : http;
    const req = proto.get(url, { headers: { 'User-Agent': 'Mozilla/5.0' } }, (res) => {
      // Follow 301 / 302 redirects (IRS does this a lot)
      if (res.statusCode === 301 || res.statusCode === 302) {
        fs.unlinkSync(dest);
        return download(res.headers.location, dest).then(resolve).catch(reject);
      }
      res.pipe(fs.createWriteStream(dest));
    });
    req.setTimeout(30000, () => { req.destroy(); reject(new Error('Timeout')); });
  });
}

async function runPool(tasks, concurrency) {
  let i = 0;
  async function worker() {
    while (i < tasks.length) await tasks[i++]();
  }
  await Promise.all(Array.from({ length: concurrency }, worker));
}
Simple. No dependencies beyond Node stdlib. The 1,421 PDFs landed in ./data/ in a couple of hours.
<a id="qa-generation"></a>20,000 Q&A Pairs — Two Very Different Roads
Two pipelines—free local Qwen and cheap Claude Haiku API—each turned IRS PDFs into about 10,000 Q&A pairs, totaling 20,000.
With 1,421 PDFs on disk, the next problem was converting raw tax law into structured training data. I ran two pipelines in parallel so I could compare them honestly.
Road 1: Qwen 3 32B via Ollama — Local, Zero Cost
SYSTEM_PROMPT = """You are an expert at reading IRS tax documents and
generating high-quality question-answer training data.

RULES:
1. Every question MUST include the form name "{form_name}"
2. Generate exactly 35 diverse Q&A pairs
3. Mix question types: Factual, Procedural, Eligibility, Field-specific, Definition
4. Answers must be accurate based ONLY on the document content

OUTPUT FORMAT:
Return ONLY valid JSONL. One JSON object per line:
{{"messages": [{{"role": "system", "content": "..."}},
               {{"role": "user",   "content": "question"}},
               {{"role": "assistant", "content": "answer"}}]}}"""
The PDF-to-markdown step used pymupdf4llm — it strips headers, footers, and page numbers while preserving tables and field labels, which is exactly what you need for IRS forms with their dense columnar layouts.
Results:
- 200 documents processed
- ~10,000 Q&A pairs
- Time: 20 hours running on my Mac
Road 2: Claude Haiku via API — Fast, ~$5
# generate_qa_claude.py — same logic, different backend
client = anthropic.Anthropic()

response = client.messages.create(
    model="claude-haiku-4-5-20251001",
    max_tokens=4096,
    system=SYSTEM_PROMPT,
    messages=[{"role": "user", "content": f"PDF content:\n\n{pdf_markdown}"}]
)
Results:
- 241 documents processed
- ~10,000 Q&A pairs
- Time: 2 hours
The 10x speed difference is the API tax — you pay in dollars instead of electricity and wall-clock time. The Haiku API cost for the full run was ~$5. Completely negligible.
Pipeline Comparison
|
Qwen 3 32B (Ollama) |
Claude Haiku (API) |
| Cost |
$0 |
~$5 |
| Documents |
200 |
241 |
| Q&A pairs |
~10,000 |
~10,000 |
| Wall-clock time |
20 hours |
2 hours |
| Quality |
Good |
Good |
| Verdict |
Free but slow |
10× faster, negligible cost |
I also ran a targeted Top-100 pass — curated by filing volume, because Form 1040, W-2, and Schedule C are filed by hundreds of millions of people and deserve extra coverage:
# generate_qa_top100.py
TOP_100_PDFS = [
    "f1040.pdf",    # ~150M filed annually
    "fw2.pdf",      # ~250M W-2s issued annually
    "f1040sc.pdf",  # Schedule C — self-employment income
    "f1040sa.pdf",  # Schedule A — itemized deductions
    # ... 96 more
]
# 80/20 train/test split
Total: ~20,000 Q&A pairs across both pipelines, grounded in actual IRS language.
<a id="finetuning"></a>Fine-tuning Gemma 4 — Three Failures and a Win
Three fine-tuning attempts on Gemma 4 succeeded in training but kept failing at ONNX conversion due to tooling gaps.
With training data in hand, I kicked off the fine-tune. I kept it to ~1,000 Q&A pairs for the first run — enough to validate the workflow without babysitting a 20-hour GPU job.
Attempt 1 — Local Mac fine-tune:
Worked. But the output format was wrong for ONNX conversion and I hit a dead end trying to massage checkpoints.
Attempt 2 — Google Colab:
Moved everything to Colab. Fine-tune ran cleanly. ONNX conversion still failed. optimum (Hugging Face's conversion toolkit) had broken support for Gemma 4 architecture — it simply didn't know what to do with the new attention pattern.
Attempt 3 — Unsloth + Gemma 4 on Colab:
Unsloth handles the memory + speed side of fine-tuning and has first-class Gemma 4 support. The fine-tune ran, the model pushed to Hugging Face. Progress — but the ONNX conversion problem was still waiting downstream.
<a id="onnx-wall"></a>The ONNX Wall
The project stalled because Hugging Face's official conversion tool could not turn the Gemma 4 model into the ONNX format browsers need to run it.
This is where the project hit its honest blocker. To run inference in the browser with Transformers.js, you need an ONNX model. And in April 2025, optimum — Hugging Face's official conversion tool — did not support Gemma 4.
The only ONNX version of Gemma 4 publicly available online was apparently created with an internal Hugging Face script. I messaged the team asking for the script. Nothing back yet.
Parallel Plan B: found an open PR for Gemma 3 ONNX conversion, and with Claude's help started patching the architecture differences for Gemma 4. Still in progress.
This is the real engineering constraint of the project. It's not a product limitation or a design choice — it's just a tooling gap that will close. When it does, the fine-tuned tax-specific model slots straight into the same browser runtime.
<a id="plan-b"></a>Plan B: RAG in the Browser
When fine-tuning was blocked, injecting form-specific Q&A into the prompt at inference time let the browser LLM work without a server.
While the ONNX path was blocked, the demo still had to work. The workaround is clean — and honestly has real advantages of its own.
Instead of a fine-tuned model, inject the form-specific Q&A at inference time. A lightweight RAG pattern, entirely in-browser, no server.
For the 8 POC forms (W-2, 1099-MISC, 1099-NEC, 1099-INT, 1099-DIV, 1040, Schedule A, Schedule B), I pulled the relevant PDFs from the 1,421-document list and generated targeted Q&A. That data lives in data.json, and when the user selects a form, the app assembles the context prompt:
// ai.js — analyseForm
const systemPrompt =
  'You are a concise IRS tax expert. Answer in 2–3 sentences maximum. Be direct and practical.';

const userPrompt =
  `I am a tax preparer reviewing IRS Form ${formKey}. ` +
  `It has ${issues.length} documented known issues:\n\n${issueLines}\n\n` +
  `What is the single most critical risk a preparer must watch for on this form? Be direct.`;

const inputs = aiProcessor.apply_chat_template(
  [{ role: 'system', content: systemPrompt },
   { role: 'user',   content: userPrompt  }],
  { tokenize: true, add_generation_prompt: true, return_dict: true }
);
This means:
- The base Gemma 4 ONNX model handles language generation.
- The injected Q&A gives it the form-specific facts it needs.
- No fine-tune required. No server call required.
The tradeoff: context window size limits how much Q&A you can inject per prompt. The fine-tuned route solves that permanently — the knowledge is baked in, not carried in the prompt. But for a POC? RAG works beautifully.
This is the generic deployment pattern. Swap the IRS Q&A for any structured knowledge base — medical billing codes, HR policy documents, legal precedents, product manuals, customer support FAQs. The model is the engine; the domain JSON is the fuel. The architecture is identical regardless of the domain.
<a id="the-app"></a>The App — What Actually Ships
The tax-form UI is a plain vanilla JS app where an in-browser model streams per-field help and risk analysis with no server calls.
The UI is a single-page vanilla JS app — no React, no build step, no bundler. Just HTML, a few ES modules, and WebGPU.
app/
  index.html        ← shell
  js/
    ai.js           ← model loading + streaming inference
    data.js         ← form definitions + Q&A + known-issues database
    renderer.js     ← dynamic form field rendering
    nav.js          ← sidebar, chat panel, AI banner wiring
  css/
    poc.css         ← styling
What you get:
- Sidebar navigation — forms grouped by category (W Forms, 1099 Series, 1040 Family, Schedules)
- Live form rendering — every field rendered dynamically from the
FORMS data structure, with section dividers and IRS-style field labels
// data.js — this is what drives the form renderer
'W-2': {
  title: 'W-2 — Wage and Tax Statement',
  meta: 'Tax Year 2024  ·  Dept. of the Treasury — IRS',
  sections: [
    { label: 'Wages & Withholding', fields: [
      { box: '1',  label: 'Wages, tips, other compensation', type: 'number', ph: '0.00' },
      { box: '2',  label: 'Federal income tax withheld',     type: 'number', ph: '0.00' },
      { box: '12a', label: 'Codes (see back of form)',       type: 'text',   ph: 'e.g. DD 1234.00' },
    ]},
    // ...
  ],
}
- Per-field AI help — every form field has a
✦ button. Click it and the model explains what goes in that specific box, with zero server call.
// renderer.js — the AI button on every field
const aiBtn = document.createElement('button');
aiBtn.textContent = '✦';
aiBtn.addEventListener('click', () => {
  document.dispatchEvent(new CustomEvent('field-ai-ask', {
    detail: { box: f.box, label: f.label }
  }));
});
- Known-issues panel — a curated database of real IRS gotchas per form (e.g., Box 12 code confusion on W-2, the 1099-NEC/1099-MISC split that tripped up millions of filers in 2020)
- AI risk analysis — when you open a form with known issues, the model streams a 2–3 sentence summary of the single most critical risk a tax preparer must watch for
- Chat panel — ask anything about the current form; the model answers from injected Q&A context
- Model status bar — shows
loading… 47% or ready ✓ so the user always knows where the download stands
Feature Summary
| Feature |
How it works |
| Sidebar navigation |
Forms grouped by category (W Forms, 1099s, 1040 family, Schedules) |
| Live form rendering |
Fields rendered from FORMS data structure, IRS-style labels |
Per-field ✦ AI help |
CustomEvent → model answers from Q&A context |
| Known-issues panel |
Curated real-world gotchas per form |
| AI risk analysis |
Streamed 2–3 sentence summary on form open |
| Chat panel |
Ask anything; context = injected form Q&A |
| Model status bar |
Live download progress + ready indicator |
The streaming output is handled token by token — the UI updates live as each token arrives:
const streamer = new TextStreamerCls(aiProcessor.tokenizer, {
  skip_prompt: true,
  skip_special_tokens: true,
  callback_function: (chunk) => {
    fullResponse += chunk;
    outputEl.textContent = fullResponse;  // live update as tokens arrive
  },
});

await aiModel.generate({ ...inputs, max_new_tokens: 200, do_sample: false, streamer });
<a id="deployment"></a>Deployment — One Bash Script
The static app runs on nginx in Docker, deployed to Cloud Run with a single 8-line bash script.
The entire app is static HTML + JS. Docker + nginx + Cloud Run. Deployed by running one script:
# deploy.bash — the whole deployment in 8 lines
# 1. Build & push (no local Docker daemon needed — Cloud Build does it remotely)
gcloud builds submit --tag gcr.io/my-project/webgpu-poc --project my-project

# 2. Deploy to Cloud Run
gcloud run deploy webgpu-poc \
  --image gcr.io/my-project/webgpu-poc \
  --platform managed \
  --region us-central1 \
  --allow-unauthenticated \
  --port 8080 \
  --project my-project
The Dockerfile is as minimal as possible:
FROM nginx:alpine

COPY index.html  /usr/share/nginx/html/index.html
COPY data.json   /usr/share/nginx/html/data.json
COPY css/        /usr/share/nginx/html/css/
COPY js/         /usr/share/nginx/html/js/
COPY nginx.conf  /etc/nginx/conf.d/default.conf

EXPOSE 8080
CMD ["nginx", "-g", "daemon off;"]
The nginx config enables gzip compression (important — data.json with 8 forms of Q&A is not small) and that's it.
By April 15 at 3 p.m. — less than 36 hours after starting the data pipeline — the demo was live and shareable.
<a id="webview2"></a>The Desktop Angle — WebView2
WebView2 lets all apps on a machine share one cached copy of the model weights, so only the first app needs to download them.
One unsolved problem with the browser approach: every user downloads the model weights (~600MB) on first visit. It sits in the browser's IndexedDB and loads fast on subsequent visits — but if you open the app in a different browser, or clear site data, you download again.
The WebView2 host solves this at the OS level. One shared cache folder, every app on the machine points to it:
// MainWindow.xaml.cs
// All WebView2 instances on this machine point to the SAME folder.
// Model lives in IndexedDB inside that folder.
// App 1 downloads it → App 2, 3, 4 get it for free.
private static readonly string SHARED_UDF = Path.Combine(
    Environment.GetFolderPath(Environment.SpecialFolder.CommonApplicationData),
    "WebGPURuntime",   // C:\ProgramData\WebGPURuntime
    "Cache");          // C:\ProgramData\WebGPURuntime\Cache

private async Task InitWebViewAsync()
{
    // Create WebView2 environment pointing to shared cache
    var env = await CoreWebView2Environment.CreateAsync(
        browserExecutableFolder: null,
        userDataFolder: SHARED_UDF);

    await WebView.EnsureCoreWebView2Async(env);
    ShowCacheStatus();   // "✓ Model cache found — fast load"
    WebView.CoreWebView2.Navigate(APP_URL);
}
The ShowCacheStatus() method checks for the IndexedDB folder inside the UDF — if it's non-empty, first-run download already happened. Any subsequent app that points to C:\ProgramData\WebGPURuntime\Cache skips the download entirely. One download, machine-wide benefit.
This part is working in code but untested end-to-end. It's the next thing to validate.
<a id="measuring"></a>Measuring What We Built
Testing shows the browser model's mixed-mode answers are 93% grounded in injected context rather than hallucinated.
You can't ship a tax AI without measuring accuracy. The measure/ folder has a full evaluation harness that runs the exact same Transformers.js runtime as the browser — same model, same ONNX backend, same code path.
// evaluate_qa.mjs — metrics against the same model the browser runs
// BERTScore F1:  Semantic similarity to reference answers (not just keyword overlap)
// Faithfulness:  % of answer words found in the injected Q&A context
// Source Acc:    Correct "Source: Q&A" vs "Source: Model" attribution
// Refusal Rate:  Does it refuse out-of-scope questions?

// Out-of-scope test questions (model should refuse these — no form context)
const OOS_QUESTIONS = [
  'What is the approximate federal tax filing deadline?',
  'Can I deduct my home office on this form?',
  'What is the penalty for late filing in California?',
  'How much is the standard deduction for 2025?',
];

// Run with: node evaluate_qa.mjs --forms W-2 1040 --n 10 --mode grounded --verbose
Results
| Mode |
BERTScore F1 |
Faithfulness |
Source Acc |
Refusal Rate |
| Mixed |
0.900 |
0.9336 |
0.95 |
0% |
| Grounded |
0.885 |
0.9206 |
0.925 |
47.5% ⚠️ |
| Model |
0.873 |
0.843 |
1.0 |
0% |
Mixed mode (injected Q&A + model knowledge) scores highest on BERTScore and Faithfulness. Grounded mode (Q&A-only context) shows a 47.5% refusal rate — expected and correct behaviour: when the question falls outside the injected context, the model declines rather than hallucinating.
What Each Metric Means
| Metric |
What it measures |
Why it matters |
| BERTScore F1 |
Semantic similarity to reference answers |
Catches correct answers phrased differently |
| Faithfulness |
% of answer tokens found in injected Q&A |
Model using context, not hallucinating |
| Source Accuracy |
Correct attribution (Q&A vs base model) |
Transparency — user knows where the answer came from |
| Refusal Rate |
Refuses out-of-scope questions |
Prevents confident wrong answers |
The 0.9336 faithfulness score in Mixed mode is the headline number: 93% of every answer the model produces is grounded in the injected IRS Q&A, not base-model hallucination. That's the entire premise of the RAG approach validated quantitatively.
<a id="tech-stack"></a>Tech Stack
The browser LLM runs entirely client-side using Transformers.js, WebGPU, and a quantized Gemma 4 model cached in IndexedDB.
| Layer |
Technology |
Why |
| Browser runtime |
Transformers.js + WebGPU |
Zero server, GPU-accelerated inference |
| Model |
Gemma 4 ONNX (q4f16) |
~600 MB, fits in mid-range VRAM |
| Model cache |
Browser IndexedDB |
Single download, reused across sessions |
| PDF scraping |
Playwright (Node.js) |
JS execution support for paginated IRS table |
| PDF → markdown |
pymupdf4llm (Python) |
Preserves tables and field labels |
| Q&A generation |
Qwen 3 32B via Ollama / Claude Haiku API |
Local (free) vs fast (cheap) |
| Fine-tuning |
Unsloth + Gemma 4 on Colab |
Memory-efficient, first-class Gemma 4 support |
| UI |
Vanilla JS (no framework) |
No build step, no bundler bloat |
| Deployment |
Docker + nginx + Cloud Run |
Static files, scale-to-zero billing |
| Desktop host |
.NET WebView2 |
Shared model cache across apps on one machine |
| Evaluation |
Node.js + same ONNX backend |
Tests the actual deployed model, not a proxy |
<a id="whats-next"></a>What's Next
Next steps are converting the fine-tuned model to ONNX, validating the WebView2 desktop cache, and wiring more forms into the demo.
Three active threads:
1. ONNX conversion for the fine-tuned model. Either the Hugging Face team surfaces their internal conversion script, or the Gemma 3 PR patch gets extended to Gemma 4. When it lands, the fine-tuned tax model slots directly into the same browser runtime — and the injected context prompts shrink dramatically because the knowledge is baked in, not injected.
2. WebView2 validation. Run the desktop host end-to-end: verify the shared IndexedDB cache actually propagates across two separate .NET apps on the same machine before writing it up as a repeatable pattern.
3. More forms, more Q&A coverage. The current demo covers 8 forms. The pipeline already generated Q&A for 241 documents. Wiring the remaining ones into the app is mostly a data.js update and a browser-side context-window tuning problem.
<a id="final-thoughts"></a>Final Thoughts
Local, compressed LLMs with browser-side RAG let apps answer domain questions without per-token cloud fees after a one-time download.
72 hours. The thread this pulls on is real: the credit wall is the defining UX of AI in 2025. Every app shows you that counter. Every app eventually asks you to pay. And almost every one of those apps is answering the same finite set of questions from knowledge that doesn't change — product docs, policy PDFs, domain Q&A — yet routing every single query to a cloud API that charges by the token.
Running the model locally breaks that loop entirely.
The deployment pattern is now accessible:
- Gemma 4's TurboQuant compresses the model to ~600 MB without quality collapse
- PLE (Per-Layer Embeddings) makes a small model smarter per byte
- WebGPU + Transformers.js turns any browser tab into an inference runtime
- Browser-side RAG injects domain knowledge at inference time — no server, no API key
The user pays once (bandwidth for the model weights, once, on first visit) and gets unlimited local inference forever. Their data never leaves the device. Latency is whatever their GPU delivers, not whatever a cloud region's current load happens to be.
To build this for your domain:
- Collect your domain documents (PDFs, policies, manuals)
- Run them through the Q&A generation pipeline (Qwen 3/Ollama for free, or Claude Haiku for ~$5 per 241 docs)
- Load the Gemma 4 ONNX model in a browser tab via Transformers.js
- Inject domain Q&A as context at inference time
- Ship as a static HTML + JSON app — no server required
Tax prep is the proof-of-concept. The pattern is the product.
The one remaining gap — ONNX conversion for Gemma 4 fine-tunes — is a tooling lag, not an architectural flaw. It will close. When it does, the fine-tuned domain model replaces the base model + injected context, and the pattern becomes even cleaner: baked-in domain knowledge, zero context overhead, unlimited local inference.
Which is most of what people are currently paying API bills for.
Built with zero sleep and a lot of late-night coffee. Try the live demo (tax prep proof-of-concept): webgpu-poc-182505046910.us-central1.run.app — open browser devtools → console to watch the model download and load in real time.
Source: github.com/madhudream/webgpu-gemma4-tax
The short version
Gemma 4's release means AI models now run live in both cloud and browser, shifting frontend work rather than eliminating it.
Live demo: webgpu-poc-182505046910.us-central1.run.app → click into arena.html for the agentic playground.
A lot of frontend engineers I talk to are quietly worried. Claude writes their components. v0 ships their layouts. Cursor refactors their state. The honest question underneath: is there still a job here in two years? I think it's the wrong question. The job didn't shrink — it moved. Gemma 4 hit two targets the same week: the 26B-A4B sibling went live behind a one-line Cloudflare Workers AI binding, and the ONNX-quantized E2B sibling became small enough to live in a browser tab. Two real runtimes, both fast, both free or near-free at scale. The frontier moved with them. This is what's on the other side.
<a id="worry"></a>The Worry Underneath
The fear that AI makes frontend engineers redundant is wrong: generating a component is the floor of the job, not the frontier.
Three or four frontend engineers messaged me about this in the last month, all variations of the same theme. Claude scaffolds the component faster than they can. v0 ships a layout in one prompt. Cursor refactors a state machine while they sleep. They're not afraid of being lazy — they're afraid of being redundant. If the model can write the page, what is the page-writer for?
I want to push back on the premise. The model writing a <Button /> is not the frontier of the job. It's the floor. The frontier is everywhere the model needs help to actually run, behave, refuse, redact, recover, and ship to a real user on a real device. Most of that floor is invisible from a tutorial. All of it is frontend code now.
The rest of this post is what I built in a weekend to convince myself of that. If by the end you think "oh — this is what's left, and it's bigger than what was here before," then we agree.
<a id="the-week"></a>The Week Gemma 4 Hit Both Targets
The same week Gemma 4 launched on both Cloudflare's edge and in-browser ONNX runtimes, frontend engineers gained the job of deciding where models run.
I was watching the Gemma 4 release stream the morning of April 4 when Cloudflare's changelog dropped: @cf/google/gemma-4-26b-a4b-it was now a one-line invocation behind their env.AI binding. Same week, the browser story finally caught up: onnx-community/gemma-4-E2B-it-ONNX runs at q4f16 in ~600 MB on a mid-range integrated GPU.
Two runtimes. Same model family. Both reachable from a single page of HTML.
That changed something. For three years the deal for frontend engineers was "you call an API, you stream the response, you render markdown, you put a credit counter in the corner." Now the stack has split:
- The browser can run the model directly — your user's GPU, no server, no API token, no per-query cost. Model lives in IndexedDB after first download.
- The edge can run a much bigger sibling at single-digit-millisecond latency from anywhere on the planet, billed by the token but cheap (Workers AI: $0.10/M input, $0.30/M output).
Pick one. Or — and this is the interesting part — pick both at once and route between them per device.
Frontend engineering didn't shrink. It absorbed the inference layer. The job is no longer "render the API response." It's "decide where the model runs, manage the runtime, enforce guardrails, redact PII, and degrade gracefully when the device can't handle it."
By the Numbers
| Metric |
Value |
| Browser model |
Gemma 4 E2B ONNX (q4f16, ~600 MB) |
| Edge model |
Gemma 4 26B-A4B (4B active per token, MoE) |
| Edge cost |
$0.10/M input · $0.30/M output |
| Edge context window |
256k tokens |
| Worker code size |
2.40 KiB / 0.98 KiB gzipped |
| First-byte latency (edge) |
~200 ms cold, ~80 ms warm |
| Per-query cost (browser) |
$0.00 |
| API tokens shipped to client |
Zero (binding stays server-side) |
<a id="thin-air"></a>UI Out of Thin Air — The Thesis
Frontend engineers will stop pre-building screens and instead design the primitives and tool protocols that models assemble into UI on the fly.
Here's the part that I think most people are still missing.
For twenty years the loop was: designer ships a mock → engineer builds the components → users click the components. Every screen pre-built, every button pre-wired, every dashboard pre-decided. We shipped a frozen catalogue of UI and hoped users found their request inside it.
That loop is ending. In the near future we won't build UI and ship it. The user will say what they want, and the page will assemble itself in front of them. A chart on a 12-column grid because someone said "show me the last quarter." A filled W-2 because someone read out three numbers. A multi-card dashboard because someone said "what do you have on me." UI out of thin air, on the user's GPU, no backend round-trip.
The eight examples I built into arena.html are all variations of this one pattern. The model is not the responder — it's the assembler. The frontend's job is to give it good primitives (a chart library, a form, a doc-store, a code sandbox) and a tool protocol it can call them with. The "page" is what falls out of the loop.
If that's true, then the question "what will frontend engineers do?" rewords itself. We won't be the people who pre-decide every screen. We'll be the people who design the primitives the model assembles into screens — the components, the tool surface, the policy layer, the runtime selection, the guardrails, the recovery paths when generation gets interrupted halfway through mounting a chart.
That's not a smaller job. It's the part of the stack with the most leverage right now, and the part with the fewest tutorials.
<a id="two-runtimes"></a>The Two New Runtimes — Browser & Edge
Pick between browser GPU, edge, and cloud at load time by probing the device, since browser is free and private but edge handles weak hardware.
The mental model I keep coming back to: there are now three places an LLM can run, and the right one depends entirely on the device in front of the user.
| Runtime |
Where the GPU lives |
Per-query cost |
Privacy |
Best for |
| Cloud API (the old way) |
Provider's data centre |
$$ per token |
Data leaves device |
Anything you don't care about cost or latency for |
| Edge (Workers AI) |
Cloudflare PoP nearest to user |
$ per token |
Data hits Cloudflare, then deleted |
Big models, weak client devices, instant warm |
| Browser (WebGPU) |
User's own GPU |
$0 |
Never leaves device |
Privacy-critical, unlimited usage, predictable cost |
The browser path is unbeatable on cost and privacy when it works. The edge path is unbeatable on latency and capability when the browser can't handle it. The frontend's new responsibility is knowing which is which on every page load and choosing without asking the user.
// app/js/arena/model.js — the router
import * as webgpu from './webgpu-backend.js';
import * as cloud  from './cloud-backend.js';

export async function loadModel() {
  const sticky = pickStickyBackend();
  if (sticky === 'cloud') { chooseBackend('cloud'); return cloud.loadModel(); }

  emit('loading', 'Probing GPU…');
  const probe = await webgpu.probeWebGPU();

  if (!probe.ok) {
    console.info('[model] WebGPU probe failed:', probe.reason, '— using cloud backend');
    chooseBackend('cloud');
    return cloud.loadModel();
  }

  chooseBackend('webgpu');
  try { await loadWebGPUWithTimeout(); }
  catch (err) {
    console.warn('[model] local load failed, falling back to cloud:', err);
    chooseBackend('cloud');
    return cloud.loadModel();
  }
}
The probe checks navigator.gpu, the adapter's maxStorageBufferBindingSize (rejects < 1 GiB), and the vendor/architecture string (rejects software adapters like SwiftShader). It's three awaits and zero dependencies.
<a id="arena"></a>The Arena — Eight Live Tool-Calling Examples
Eight live examples prove one agent loop, using a plain fenced-JSON tool-call protocol, works unmodified across both browser and edge model runtimes.
I built arena.html to stress-test the runtimes against real agentic patterns. Eight examples, each a self-contained module, each exposing a tools array, a runTool dispatcher, a systemPrompt, and a setupWorkspace callback. The agent loop is example-agnostic — it accepts those as args:
| Example |
What the model orchestrates |
Why it matters |
| Chart Stitcher |
Picks a chart component + dataset, mounts it on a 12-col grid |
Tool-call basics |
| Auto Dashboard |
Fetches every dataset, packs a multi-card layout in one prompt |
Multi-step planning |
| Voice Chart |
STT → Gemma → chart, hands-free |
Web Speech API + LLM |
| Form Filler |
Fills a synthetic W-2 by calling set_field / submit_form tools |
Structured output |
| Page Q&A |
Reads sections of a sample doc and highlights its source |
Citation discipline |
| Code Sandbox |
Writes JS, runs it in a Web Worker, iterates on output |
Closed-loop coding |
| Content Safety ✦ |
Rule-based guardrails: refuse jailbreaks, off-topic, illegal-tax |
Frontend as policy layer |
| PII Prevention ✦ |
Detect + redact PII before any model ever sees it |
Frontend as privacy layer |
The tool-call protocol is plain fenced JSON — chosen over Gemma's native special-token format because it's debuggable and version-stable across both runtimes:
```tool_call
{"name": "set_field", "args": {"name": "wages_box1", "value": "180000.00"}}
```
The runtime runs the tool, replies with a tool_result block, and the loop continues until the model emits finish or speaks plain text.
What surprised me: the same agent.js loop works against both runtimes with zero per-runtime branching. The browser model and the edge model both speak the same fenced-JSON protocol. The only thing that changes is which generate() function is wired in.
Look at any one of these examples and the "out of thin air" pattern is the same: a sentence in, a configured component out, mounted in the DOM by the time the model finishes typing.
<a id="toggle"></a>The Local-vs-Edge Toggle
A topbar toggle lets you compare the local browser model against a larger edge model on the same prompt, same machine.
The arena topbar has a segmented control: Local GPU | Edge. Click it; the page reloads with a sticky preference, and the model router honours your choice.
The label next to it is the detected GPU — vendor, architecture, and maxStorageBufferBindingSize in MB. On my M1 Pro it says Apple GPU · 4096MB. On my old Intel iGPU laptop it says Intel Iris · 768MB, the Local GPU button is disabled, and the page silently picks Edge.
// arena.html topbar
<div class="arena-backend">
  <span id="gpu-info">detecting GPU…</span>
  <div id="backend-toggle" role="radiogroup">
    <button data-backend="webgpu">Local GPU</button>
    <button data-backend="cloud">Edge</button>
  </div>
</div>
The reason this matters: you can demo both runtimes side-by-side on one machine. Submit the same prompt to the Auto Dashboard preset, flip the toggle, see the latency difference, see the quality difference, see whether the bigger edge model handles a tricky tool-call sequence the browser model fumbles. Same code, same prompt, two GPUs.
For the two examples that benefit from raw model capability — content-safety classification accuracy, multi-step PII reasoning — the 26B-A4B edge model is noticeably sharper. For everything chart-and-dashboard-shaped, the browser model is plenty.
<a id="guardrails"></a>Guardrails Are Frontend Code Now
In-browser models require you to write deterministic, regex-based safety checks yourself, since there is no hidden server gateway to rely on.
When the model runs in the browser, your guardrails run in the browser too. There's no hidden gateway you can lean on. If you want to refuse a jailbreak, that's a function call you write yourself.
The Content Safety example is exactly this — a deterministic, rule-based classifier sitting in front of Gemma:
const INJECTION_PATTERNS = [
  /\b(ignore|disregard|forget)\b.{0,30}\b(previous|above|prior|earlier)\b.{0,20}\b(instructions?|prompts?|rules?)\b/i,
  /\b(system\s*prompt|developer\s*mode|jailbreak|DAN\s*mode)\b/i,
  /\bact\s+as\s+(?!a\s+(tax|cpa|accountant|preparer))/i,
  /<\|im_start\|>|<\|im_end\|>|<\|system\|>/i,
  /\boutput\s+the\s+(system|hidden|secret)\s+(prompt|message|instructions?)/i
];

function classify(text) {
  const labels = [];
  for (const re of INJECTION_PATTERNS) if (re.test(text)) {
    labels.push({ kind: 'prompt_injection', match: text.match(re)[0] }); break;
  }
  // … jailbreak, illegal_request, abusive, off_topic, tax_question
  return labels;
}
The agent's tool list exposes classify_intent, policy_decision (ALLOW | REFUSE), refuse(reason), and answer_safe(text). The model orchestrates; the regex is the actual policy. The model could try to skip the classifier — but the runtime also post-checks every answer_safe call for prompt-leak patterns (system prompt, my instructions are, <|im_start|>) and rejects the answer back at the model with a hint to retry.
That second layer is the part most people miss. Defence in depth on the frontend looks like a deterministic check around every model output, not a softer system prompt. The model can be coaxed into anything; a regex around its mouth cannot.
<a id="pii"></a>PII Stays in the Browser, Period
Sensitive data stays local because the model only ever sees redacted text, and a runtime check blocks any output containing original PII.
The PII Prevention example takes the same posture for sensitive data. Five tools:
scan_pii(text) — regex pass: SSN, credit card (Luhn-validated), email, phone, IP, EIN, DOBredact(text) — replaces every span with a <KIND_N> placeholder, returns mappingpolicy_decision(verdict, reason) — PROCEED with redacted text, or BLOCKanswer(text) — runtime asserts no original PII string appears in this outputfinish(message) — terminate
The detail that matters: the placeholder mapping never leaves the browser. The model only ever sees the redacted version. The mapping object lives in a closure inside setupWorkspace, and when the agent calls answer, the runtime defence-in-depth check looks for any original PII string in the output and rejects the call if it finds one:
case 'answer': {
  const text = String(args.text ?? '');
  const leaks = [];
  for (const orig of Object.values(lastMapping)) {
    if (orig && text.includes(orig)) leaks.push(orig);
  }
  if (leaks.length) {
    return {
      ok: false,
      error: 'answer contains original PII strings — rewrite using placeholder tokens like <SSN_1>',
      leaked: leaks
    };
  }
  report.setSafeOutput(text);
  return { ok: true };
}
When the model echoes a real SSN back into its answer (it tries — they always try), the call fails, the model gets a hint, and it rewrites the answer using <SSN_1> instead. Zero original PII tokens cross the network in either direction. On the browser path, no network at all.
This is the kind of code that used to live in a backend service. Now it lives next to the model, in the same module the model lives in. It runs on every device, for every user, with no per-request server cost.
<a id="worker"></a>The Cloudflare Worker Proxy — Five Files
A tiny five-file Cloudflare Worker keeps the Workers AI token on Cloudflare's edge, never exposing it to the browser or source code.
The edge backend is a Cloudflare Worker. The whole thing is 2.40 KiB unzipped, 0.98 KiB gzipped. Five files in a worker/ folder:
worker/
  wrangler.toml         # 12 lines
  package.json          # 9 lines
  src/index.js          # ~80 lines — the entire proxy
The Worker is the only place that touches Workers AI. It uses the env.AI binding, which authenticates against the parent account automatically — no API token in the source, no API token in the browser, ever:
export default {
  async fetch(req, env) {
    if (req.method === 'OPTIONS') return new Response(null, { headers: cors(origin) });
    const { messages, max_tokens = 512, stream = true } = await req.json();
    const result = await env.AI.run('@cf/google/gemma-4-26b-a4b-it', {
      messages, stream, max_completion_tokens: max_tokens
    });
    return new Response(result, {
      headers: { ...cors(origin), 'Content-Type': 'text/event-stream' }
    });
  }
};
Browser hits the Worker. Worker pipes Gemma 4's SSE stream back through. Token never leaves Cloudflare's edge network.
name = "webgpu-gemma-tax-proxy"
main = "src/index.js"
compatibility_date = "2026-04-01"

[ai]
binding = "AI"
wrangler deploy — done. The Worker is at a *.workers.dev URL within seconds.
<a id="thinking"></a>Killing Gemma 4's Thinking Mode
A one-line system prompt directive fully suppresses Gemma 4's built-in reasoning tokens, removing latency for agent loops without needing an SDK flag.
This is the kind of detail that took an afternoon to figure out and saves seconds per request once you do.
Gemma 4 26B-A4B ships with a built-in thinking mode. Send a prompt to @cf/google/gemma-4-26b-a4b-it cold and the SSE stream emits delta.reasoning tokens for 300+ tokens before any delta.content arrives. For a chat interface that's fine, even useful. For an agent loop that's parsing fenced tool-call JSON out of delta.content, it's pure latency tax.
The fix is one sentence in the system prompt:
const NO_THINK_DIRECTIVE = 'Reply directly. Do not think. Do not show reasoning.';

function suppressThinking(messages) {
  if (messages[0]?.role === 'system') {
    return [
      { ...messages[0], content: `${NO_THINK_DIRECTIVE}\n\n${messages[0].content}` },
      ...messages.slice(1)
    ];
  }
  return [{ role: 'system', content: NO_THINK_DIRECTIVE }, ...messages];
}
Verified empirically: zero delta.reasoning tokens after that change. Content streams immediately. The model still produces correct fenced tool calls; it just stops narrating its way there.
Lesson: when the model has a runtime feature you don't want, sometimes the cheapest off-switch is a sentence in the system prompt. No SDK flag necessary.
<a id="stack"></a>The New Frontend Stack
One app can run on either a local browser model or an edge model, because only model.js decides which backend's generate() to call.
For anyone wiring this kind of architecture for the first time, the layers I ended up with:
| Layer |
Browser path |
Edge path |
| Model |
Gemma 4 E2B ONNX (q4f16) via Transformers.js |
Gemma 4 26B-A4B via Workers AI |
| Auth |
None (model is local) |
env.AI binding (no token in client) |
| Streaming |
Custom TextStreamer callback |
OpenAI-compatible SSE (delta.content) |
| Tool protocol |
Fenced JSON (```tool_call blocks) |
Same |
| Probe |
navigator.gpu adapter limits + vendor allowlist |
n/a |
| Cache |
IndexedDB, ~600 MB once |
Cloudflare warm cache |
| Cost |
Bandwidth on first load |
$0.40/M tokens combined |
| Privacy |
Data never leaves device |
Data hits CF edge, then deleted |
| Guardrails |
Regex / Luhn / post-checks in JS |
Same regex, runs in browser before send |
| UI router |
model.js selects backend at load time |
Same module, same UI |
The crucial property: the application code on the page does not change between runtimes. The agent loop, the examples, the tool definitions, the guardrails — all identical. Only model.js knows which generate() is in use. The router pattern is what lets you ship one app and have it adapt itself to whatever GPU the user happens to have.
<a id="frontier"></a>The New Frontier of the Job
The frontend job shifts from writing UI components to managing where models run, what they see, and what they're allowed to say.
So — back to the worried frontend engineers. What will we actually do?
Yes, an LLM can scaffold a button faster than you can. That's not the frontier of the job anymore. The frontier is everywhere the model needs help to actually run on a real device, behave under adversarial input, and assemble UI for a real user. Six things:
- Runtime selection. Probing
navigator.gpu, knowing what q4f16 means, knowing the trade-offs between a browser model and an edge model on a phone with weak silicon vs a desktop with a discrete GPU. Choosing without asking the user.
- Guardrails as code. Regex classifiers, Luhn checks, redaction maps with closures, defence-in-depth post-checks. The work that used to live in backend services now lives next to the model on the user's device.
- Tool protocols. Fenced JSON, native function-calling tokens, JSON-schema-validated args. The model is calling code; the frontend is the dispatcher. Every primitive you expose is a verb the model can use to assemble UI.
- Cost shaping. Knowing that
delta.reasoning is 300 tokens you don't need, that a stop_strings flag saves 5–10 tokens per tool call, that an unbounded max_tokens parameter is an attack surface.
- Edge-worker plumbing. An 80-line worker is now a normal part of a frontend project, not a "backend thing." It's the place your secrets live so they never reach the page.
- Graceful degradation across runtimes. A page that runs the local model when it can, the edge model when it can't, the cloud API when neither's available — and never asks the user which.
Notice what's not on this list: writing the <Button />. That's the floor now, and the floor is fine — let the model have it. What's above the floor is where the model lives, when it runs, what it sees, what it's allowed to say back, and what primitives it has to assemble UI from. That's the layer where the leverage is. That's the layer with no tutorial yet.
We're not being replaced. We're being asked to design UI in a new register — one where inference is part of the page, the GPU is part of the stack, and a 600-megabyte model is a normal thing to ship to a user. That's not a smaller job. It's a different one.
<a id="final"></a>Final Thoughts
Frontend engineers can now choose between local, edge, or cloud AI runtimes from a few lines of code in the browser.
Three years ago "AI feature" meant "OpenAI API key in your environment, credit counter on the dashboard." Today it means a 600 MB ONNX file in IndexedDB, a wrangler deploy away from a 26B model on the edge, and a frontend module that decides between them in three awaits.
The credit wall doesn't have to exist for most products. The cloud-API-only architecture isn't the architecture anymore — it's one architecture, and now there are two more sitting next to it, both within a frontend engineer's reach without leaving the browser tab.
What you do with that depends on what you're building. But the part that excites me: for a huge class of apps — domain-bounded knowledge work, form-filling, data exploration, customer-support assistants — the right architecture is now the local one, with an edge fallback for the user whose laptop can't quite handle it. And both of those live in code you write as the frontend engineer.
If you've been waiting for the moment when "frontend" stopped meaning "the part above the API call," this is it. The API moved into the page. The page moved onto the GPU. The job got bigger in the most interesting direction it's expanded in years.
Try the demo: webgpu-poc-182505046910.us-central1.run.app. Open the arena, flip the Local GPU / Edge toggle, watch the same prompt run on two completely different runtimes from the same six lines of router code. Then look at your own product and ask: which runtime should this be? — and what UI should fall out of thin air when the user just says what they want?
You don't have to pick one.
Built late at night, again. Thanks to the Gemma team for shipping a model that fits both runtimes, and to Cloudflare for making the edge path a one-line binding.